Microsoft Decision-1 Scores Options: Your App Controls the Action
A model can choose the best-looking route without being the system that carries it out. Microsoft-Decision-1 is useful to understand through that distinction. Microsoft introduced it on October 9, 2026, for scoring decisions such as routing and classification. It is not a replacement for a conversational assistant.
Microsoft’s dated announcement and evaluation claims
Give it a closed question, not an open-ended writing task
The Foundry catalog describes a text model that assigns probabilities to answer options supplied with the input. It supports classification, ratings and evaluation against a rubric. The catalog marks the model as Preview. It also explains that Microsoft post-trained it from Qwen3.5-9B.
That makes a question such as “Which support queue fits this message: delivery, billing, technical support, or insufficient information?” a closer fit than “Write the customer a helpful reply.” The queue example here is an illustration of application design, not a tested product integration.
Foundry model catalog: capabilities, lifecycle and limits
Keep the scoring step separate from the action
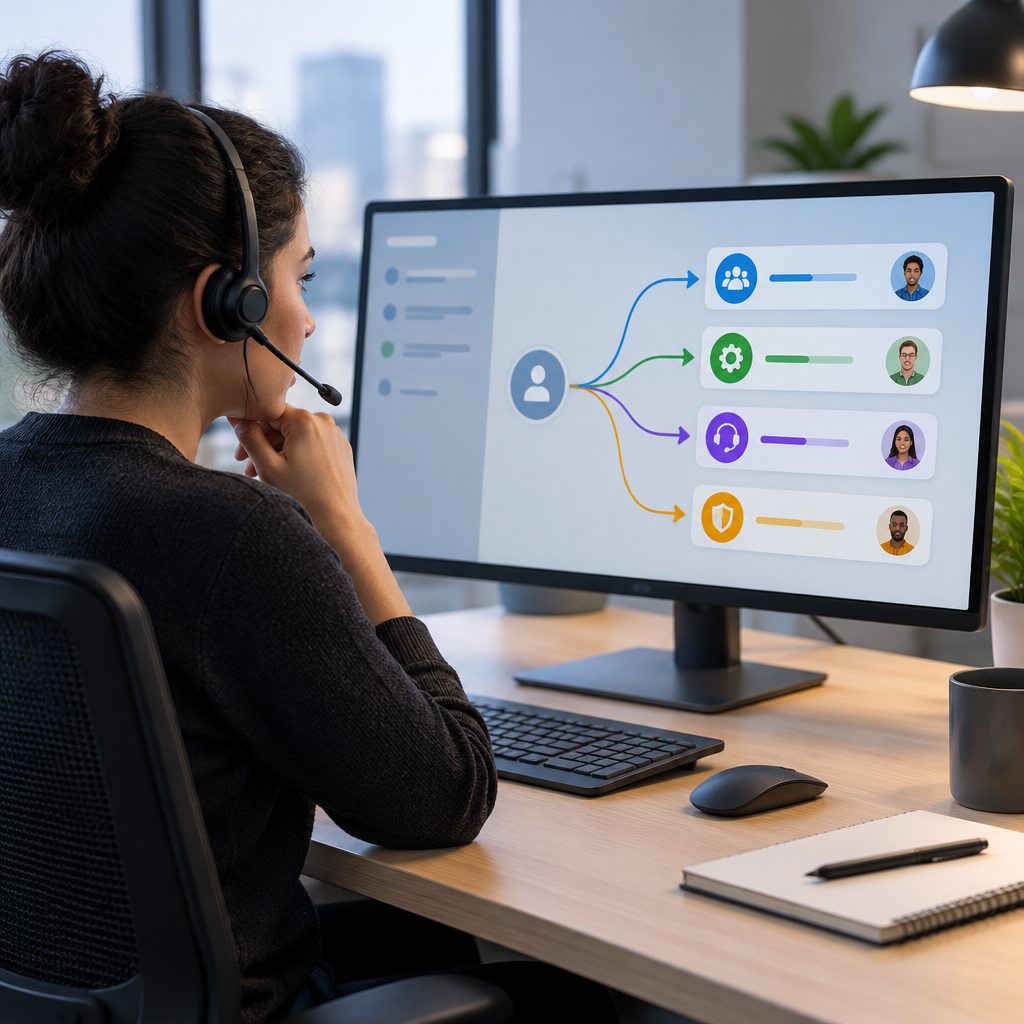
Imagine a support workflow with four stages. First, your application gathers the message and the permitted queue definitions. Second, it asks the model to score those options. Third, application rules check whether routing is permitted and whether review is needed. Fourth, the application records or carries out the approved routing action.
A high score should not silently create permissions that the application never granted. Keep the available actions explicit. For example, routing a ticket internally and sending a message to a customer are different actions; one should not automatically authorize the other. Preserve the original input, option definitions, model version and final action in your trial records so you can explain an unexpected result.
Treat a threshold as something to evaluate
Microsoft presents calibration and speed results from its own evaluations. Those are vendor findings, rather than measurements of your workflow. A probability score is useful evidence for a routing policy, but a single confident answer cannot establish how reliable that policy will be on tomorrow’s messages.
Build a small labeled evaluation set with routine requests, ambiguous messages and cases that do not fit any queue. Reserve examples that you do not use while adjusting instructions. Compare a simple keyword baseline with model routing, and record mistaken routes, review workload and total processing time. Select a threshold only after looking at these trade-offs; this article does not prescribe a universal cutoff.
Know when to hand off
The catalog rules out open-ended generation and says the model does not provide explanatory rationales. It permits an insufficient-information option and puts responsibility for thresholds, escalation and downstream safeguards on the integrating application. It also excludes using the model as the sole decision-maker for consequential decisions about people, including employment, credit and healthcare.
Start with a reversible internal classification trial. Keep unclear cases visible to a person, inspect disagreements and decide whether the extra scoring step improves your actual process. The practical question is not whether every workflow needs another model. It is whether a clearly defined decision, measured against a baseline, becomes more useful to the people operating it.