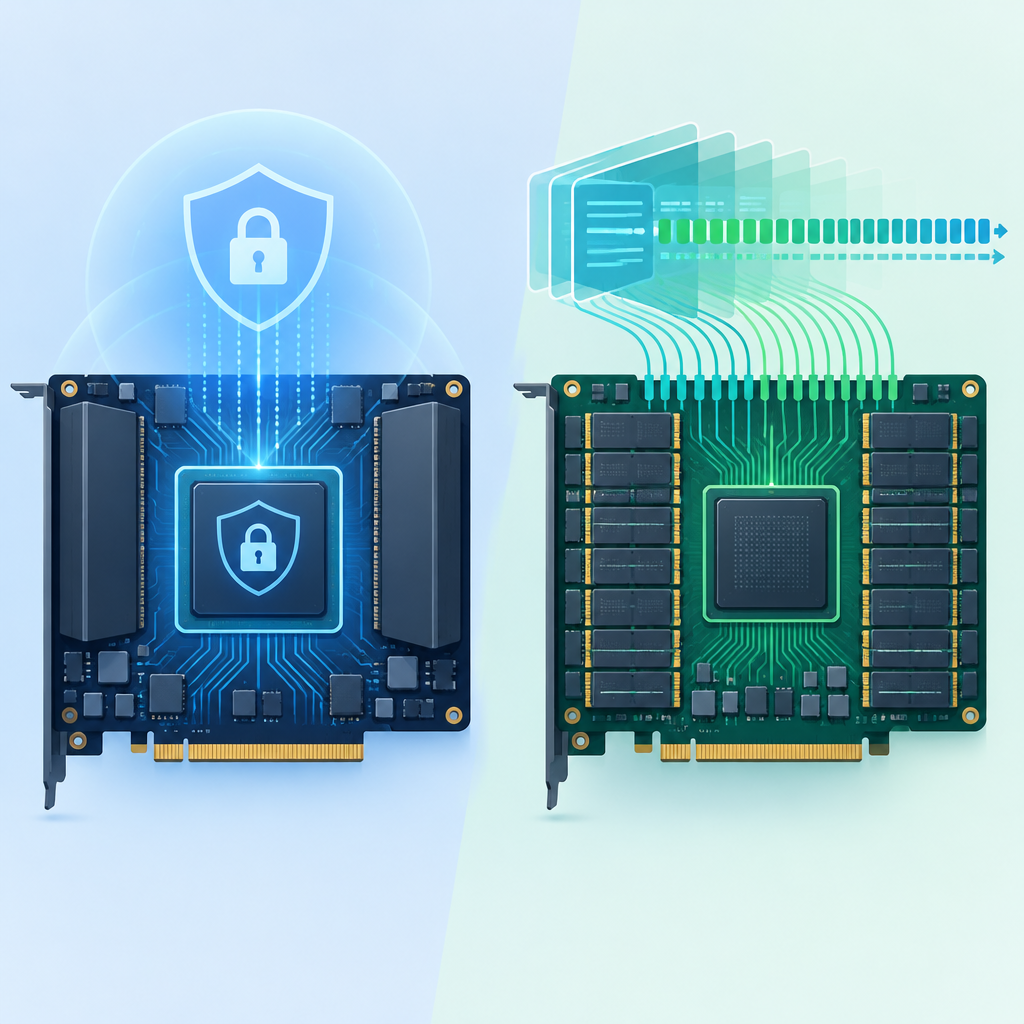
Google’s announced TPU 8tx and TPU 8i Max target different bottlenecks, so the right choice depends on the workload you are trying to optimize. In broad terms, 8tx is positioned for confidential inference and smaller-scale training scenarios, while 8i Max is aimed at memory-heavy inference, especially long-context use cases. The November 9, 2026 announcements describe these systems, but an announcement alone does not establish regional availability, pricing, or compliance fit for any specific customer.
Official Google Cloud announcement: TPU 8tx and TPU 8i Max
Official Google blog announcement: TPU 8i Max and 8tx
What TPU 8tx appears to be for
Google’s 8tx is described as a confidential inference option that also supports smaller-scale training. The confidential angle matters when the workload includes sensitive prompts, proprietary model inputs, or regulated data that must stay within a trusted execution and attestation framework. Google also says 8tx uses custom AMD CPU hosts, which may be relevant for system integration and security planning, but the announcement should not be read as a blanket claim about performance or compliance in every deployment.
If your main concern is protecting sensitive inputs while running inference, 8tx is the more direct fit to evaluate. In practical terms, that means checking whether your application requires attestation, which regions are acceptable for your data handling policy, and how your orchestration stack will prove trust before sending prompts or embeddings into the system.
What TPU 8i Max appears to be for
TPU 8i Max is framed as a memory-heavy inference platform for workloads that benefit from more room for model state and longer contexts. Google describes a dual-chip design and positions the system around long-context inference, where memory capacity and memory bandwidth can become the real limiting factors. That distinction is important: bandwidth affects how quickly data can move, while capacity determines how much can be kept resident. They are not the same bottleneck, and more of one does not automatically solve the other.
Google’s claims about relative compute, SRAM, and HBM bandwidth may be useful as directional signals, but they should be treated as vendor claims unless you validate them in your own workload. A system can look stronger on paper and still fail to improve your application if your bottleneck is elsewhere, such as tokenization, batching strategy, network overhead, or host-side scheduling.
Do not assume every workload doubles throughput
It is tempting to read a dual-chip design and assume linear scaling, but inference rarely behaves that neatly. Throughput gains depend on model size, sequence length, batching, KV-cache pressure, concurrency, and whether the workload is compute-bound or memory-bound. Some applications may benefit significantly from 8i Max, while others may see only modest gains or even regress if their serving stack is not tuned for the hardware.
The same caution applies to 8tx. Confidentiality features can introduce operational constraints, and those constraints may matter more than raw speed for some teams. If your top priority is not security-sensitive inference, the added complexity may not be justified.
A practical test plan for 8tx
- Document which inputs are sensitive before testing: prompts, RAG passages, embeddings, logs, and any derived outputs.
- Verify attestation and trust requirements with your security team before moving data into the environment.
- Check whether the target region satisfies your residency, policy, and governance requirements.
- Compare the same model and prompt set in approved test environments. Use synthetic inputs for any baseline that does not meet your confidentiality requirements.
- Measure operational overhead separately from model quality so you can see what the security layer changes.
A practical test plan for 8i Max
- Test representative context lengths, not just short prompts, because long-context behavior is the point of this system.
- Measure time to first token, tail latency, and sustained throughput under realistic batching.
- Include several concurrency levels to see where memory pressure begins to dominate.
- Use your actual serving stack, or as close as possible, instead of a toy benchmark.
- Track whether the system improves user-visible responsiveness, not just raw tokens per second.
How to choose between them
Evaluate 8tx first if sensitive data must stay protected while inference runs. Evaluate 8i Max first if long prompts and large caches strain memory or slow responses. Before making a deployment decision, verify availability, pricing and how the system performs on your own traffic.
The most useful next step is not to ask which chip is “faster” in general, but to ask which constraint is hurting your application today. Security constraints point toward 8tx. Memory and latency behavior under long prompts point toward 8i Max. The better answer is the one that matches your bottleneck, your region rules, and your actual production traffic.